A Comparative Study of Dynamic Programming and Reinforcement Learning in Finite-Horizon Dynamic Pricing
发表于 2026年4月15日上传于 2026年4月16日
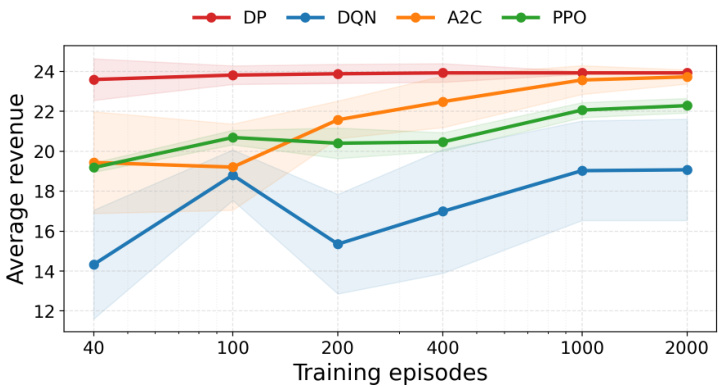
This paper empirically compares fitted dynamic programming (DP) and model-free reinforcement learning (DQN, A2C, PPO) on four finite-horizon dynamic pricing environments (single and multi-typology, with/without cumulative revenue constraints), evaluating revenue, stability, constraint satisfaction and computational scaling; results show DP is a stable, high-performing benchmark while RL (PPO/A2C) can approach DP given sufficient episodes but exhibits higher variance and slower convergence in low-data or higher-dimensional settings .
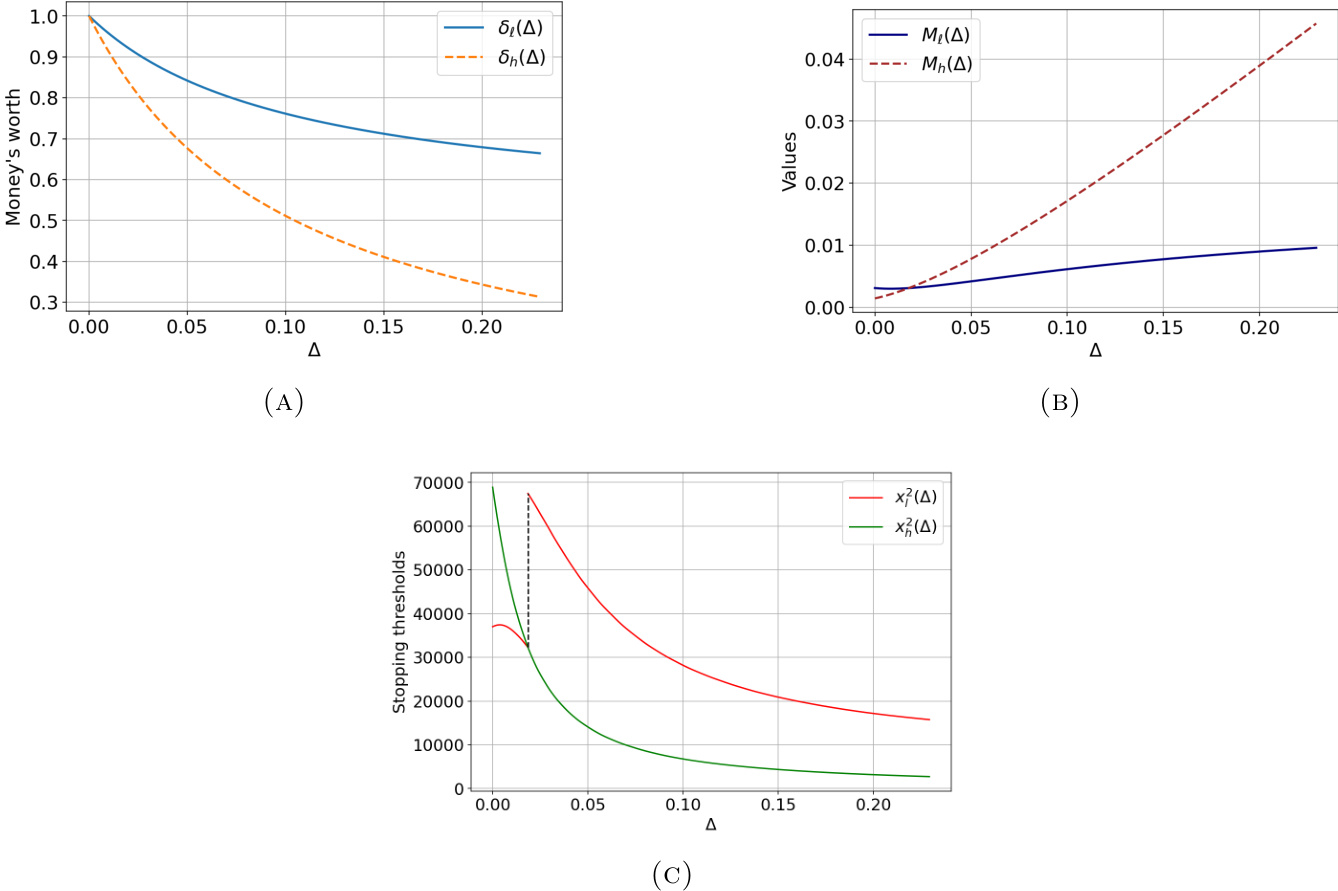
OPTIMAL ANNUITIZATION TIME UNDER A MORTALITY SHOCK
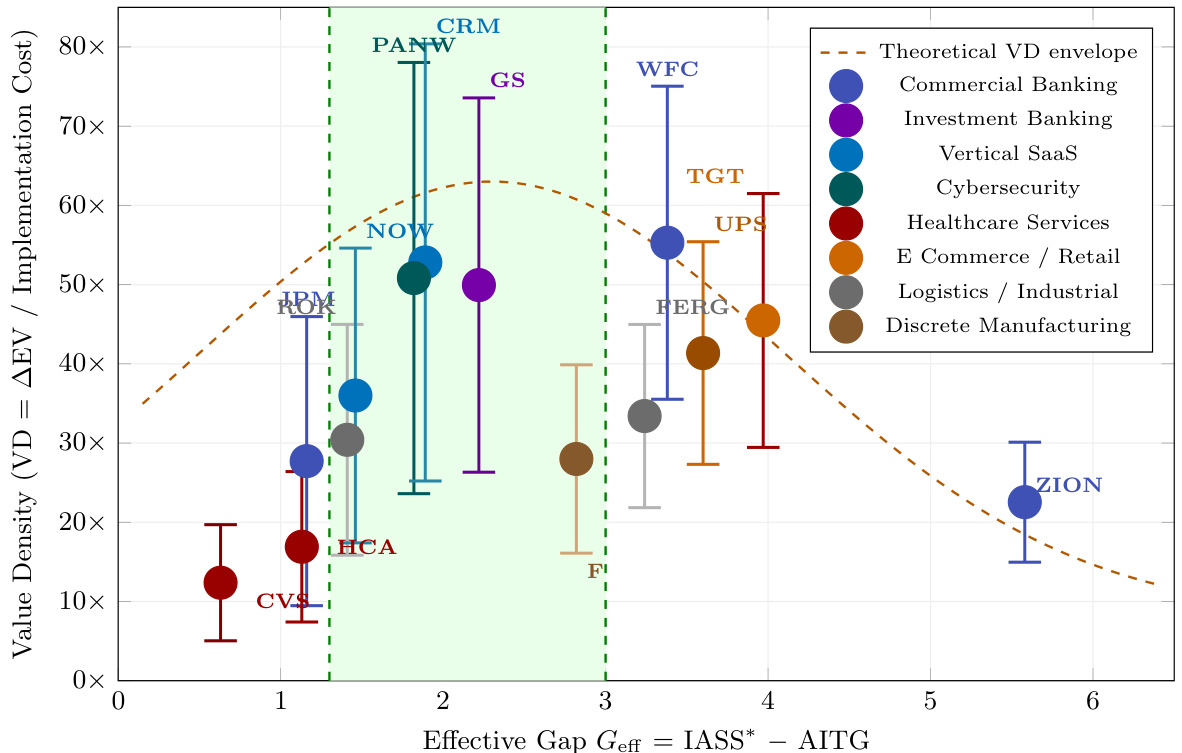
The AI Transformation Gap Index (AITG): An Empirical Framework for Measuring AI Transformation Opportunity, Disruption Risk, and Value Creation at the Industry and Firm Level